Nota: esta página es una traducción automática y puede contener errores o frases poco naturales. Si algo no queda claro, consulta el original en inglés.
Notas de investigación
Avances preliminares de investigación, ideas especulativas y notas breves
Implementing and Evaluating a Basic Per-Action Monitor for Safer Evals
27 de septiembre de 2026

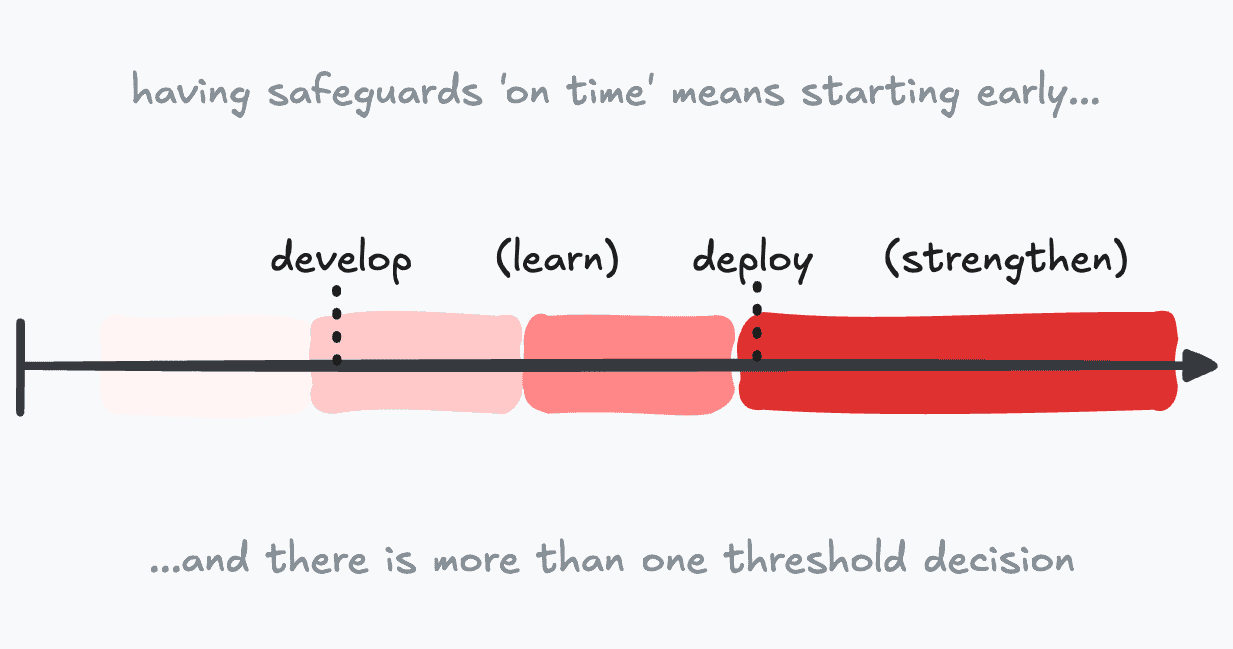
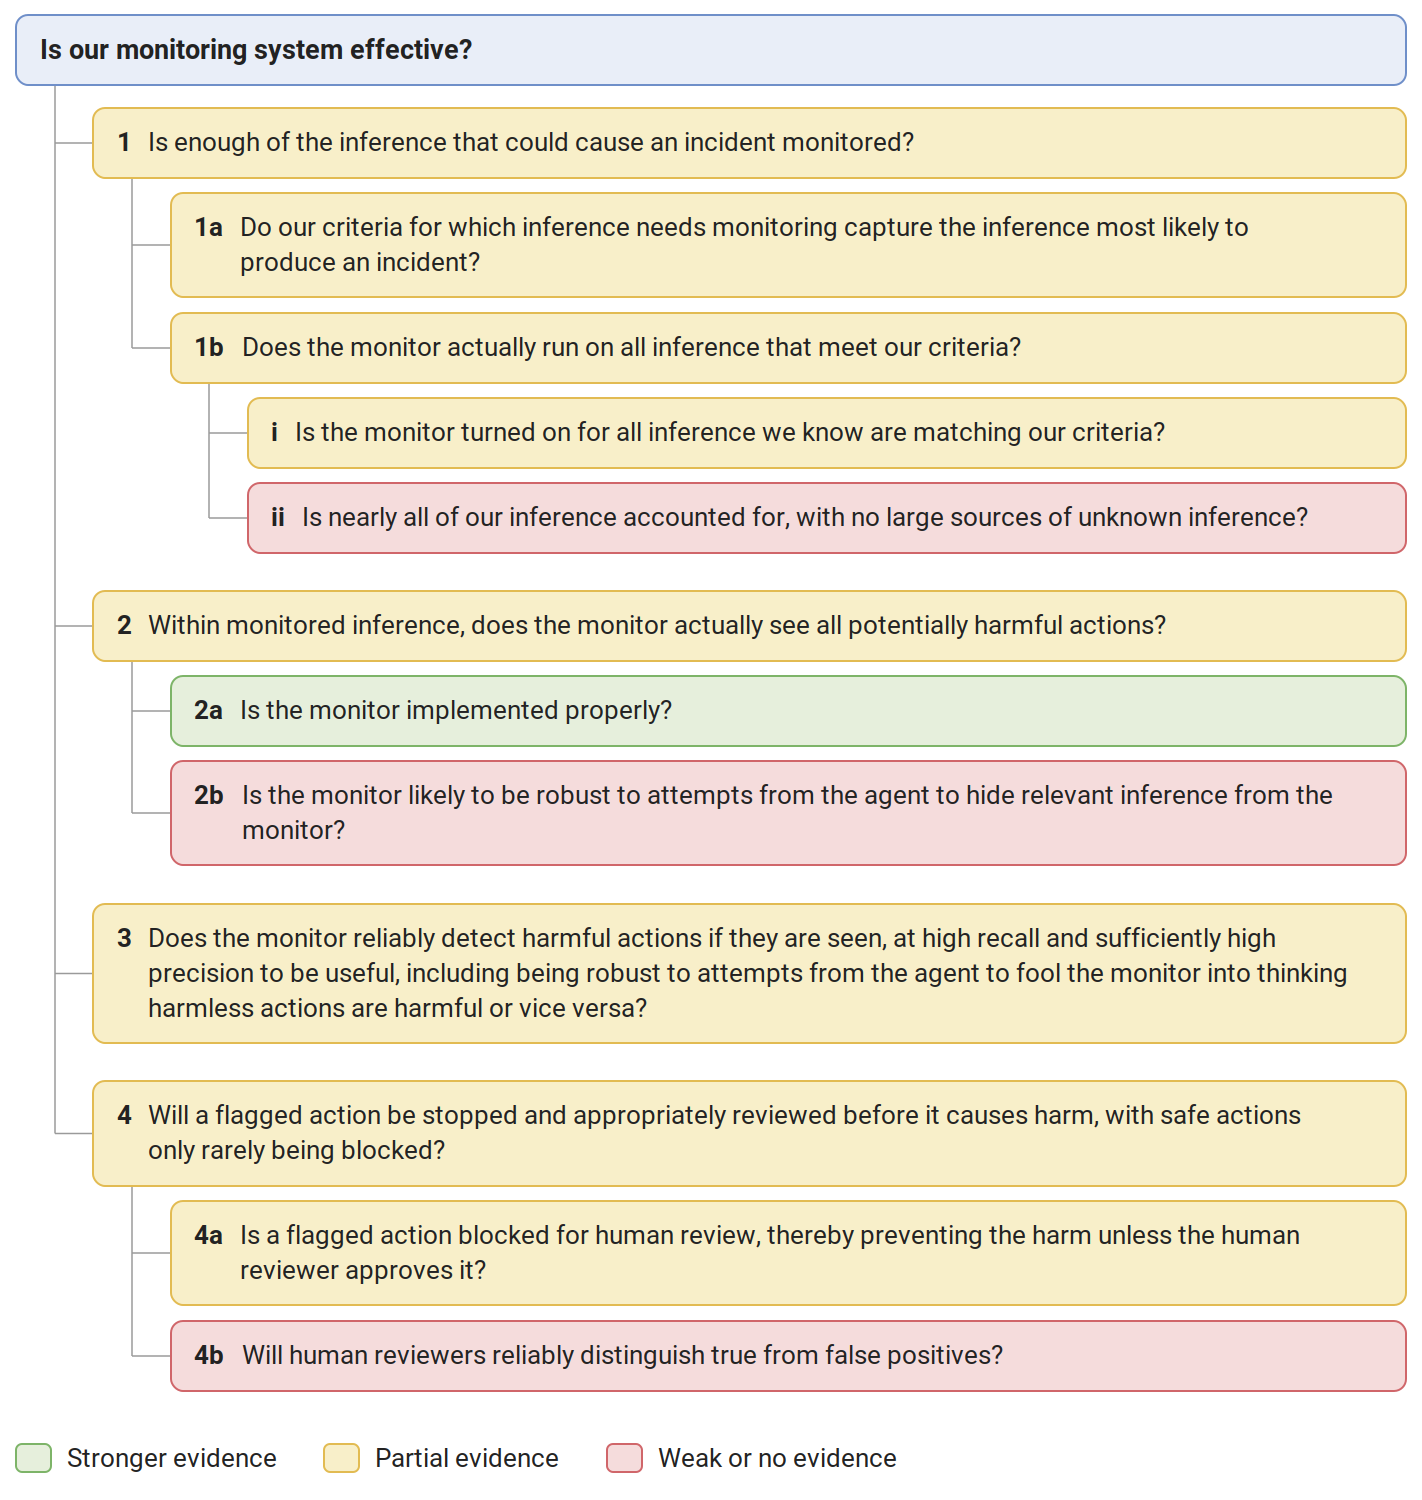
Reilly Haskins, Rif A. Saurous, Nate Rush, Neev Parikh, and Beth Barnes lay out the claims that would need to hold for their per-action blocking monitor to be effective, the evidence for each claim, and the gaps that remain.

Leer en inglés
Have We Seen an Acceleration in Discoveries?
14 de agosto de 2026

Tom Cunningham and Nate Rush look at public time series of discoveries in cyber, math, and algorithms to see whether LLMs have accelerated the discovery rate.

Leer en inglés
Metrics of Agent Ability
24 de julio de 2026

Tom Cunningham surveys metrics for comparing AI agent capability as performance changes with expenditure and relative to human performance.

Leer en inglés
The Economics of Recursive Self-Improvement
22 de julio de 2026

Parker Whitfill and Tom Cunningham highlight context and takeaways from a new paper modeling how AI may accelerate AI R&D, and whether feedback effects could be strong enough for self-sustaining acceleration.

Leer en inglés
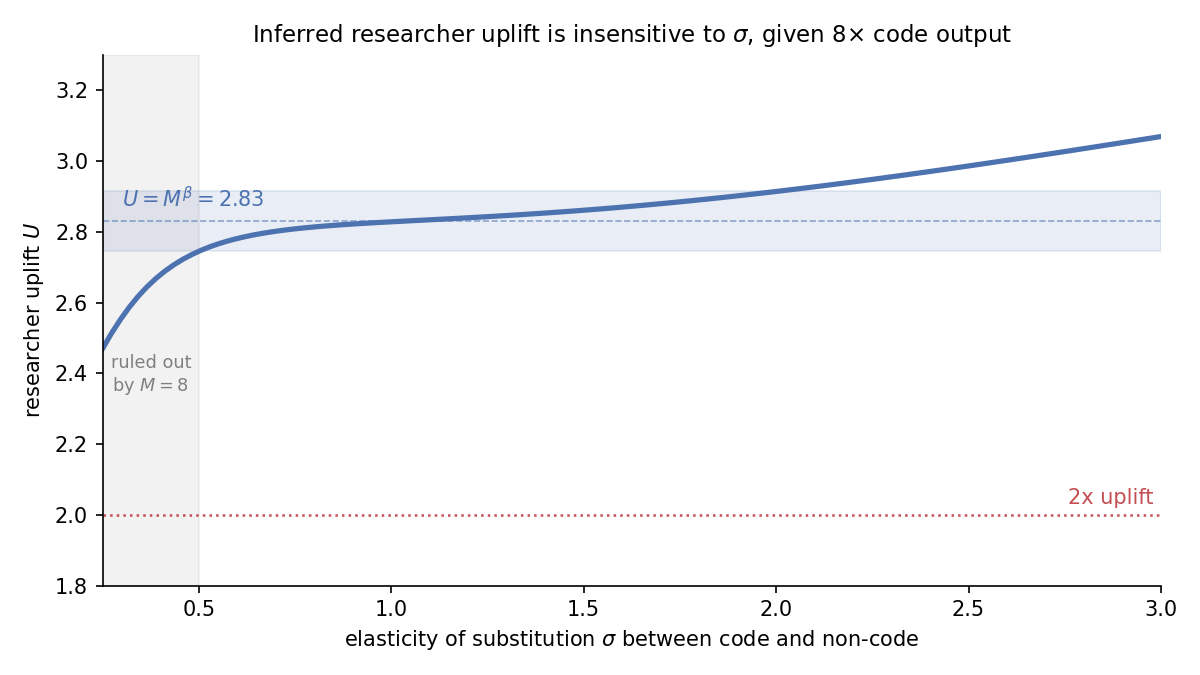
Because 8 ≈ e², Anthropic's researcher uplift is plausibly >2x
8 de julio de 2026

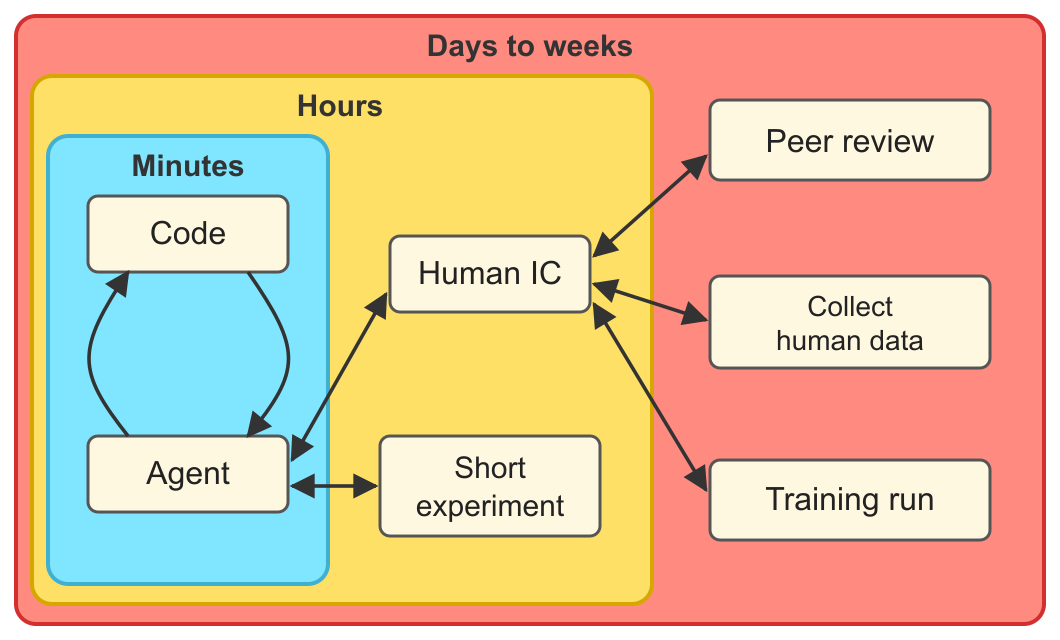
Anthropic reported that contributors merge 8x as much code per day as before AI. Thomas Kwa argues that under standard economic modeling assumptions, this implies the uplift of individual Anthropic researchers from coding agents alone is above 2x.

Leer en inglés
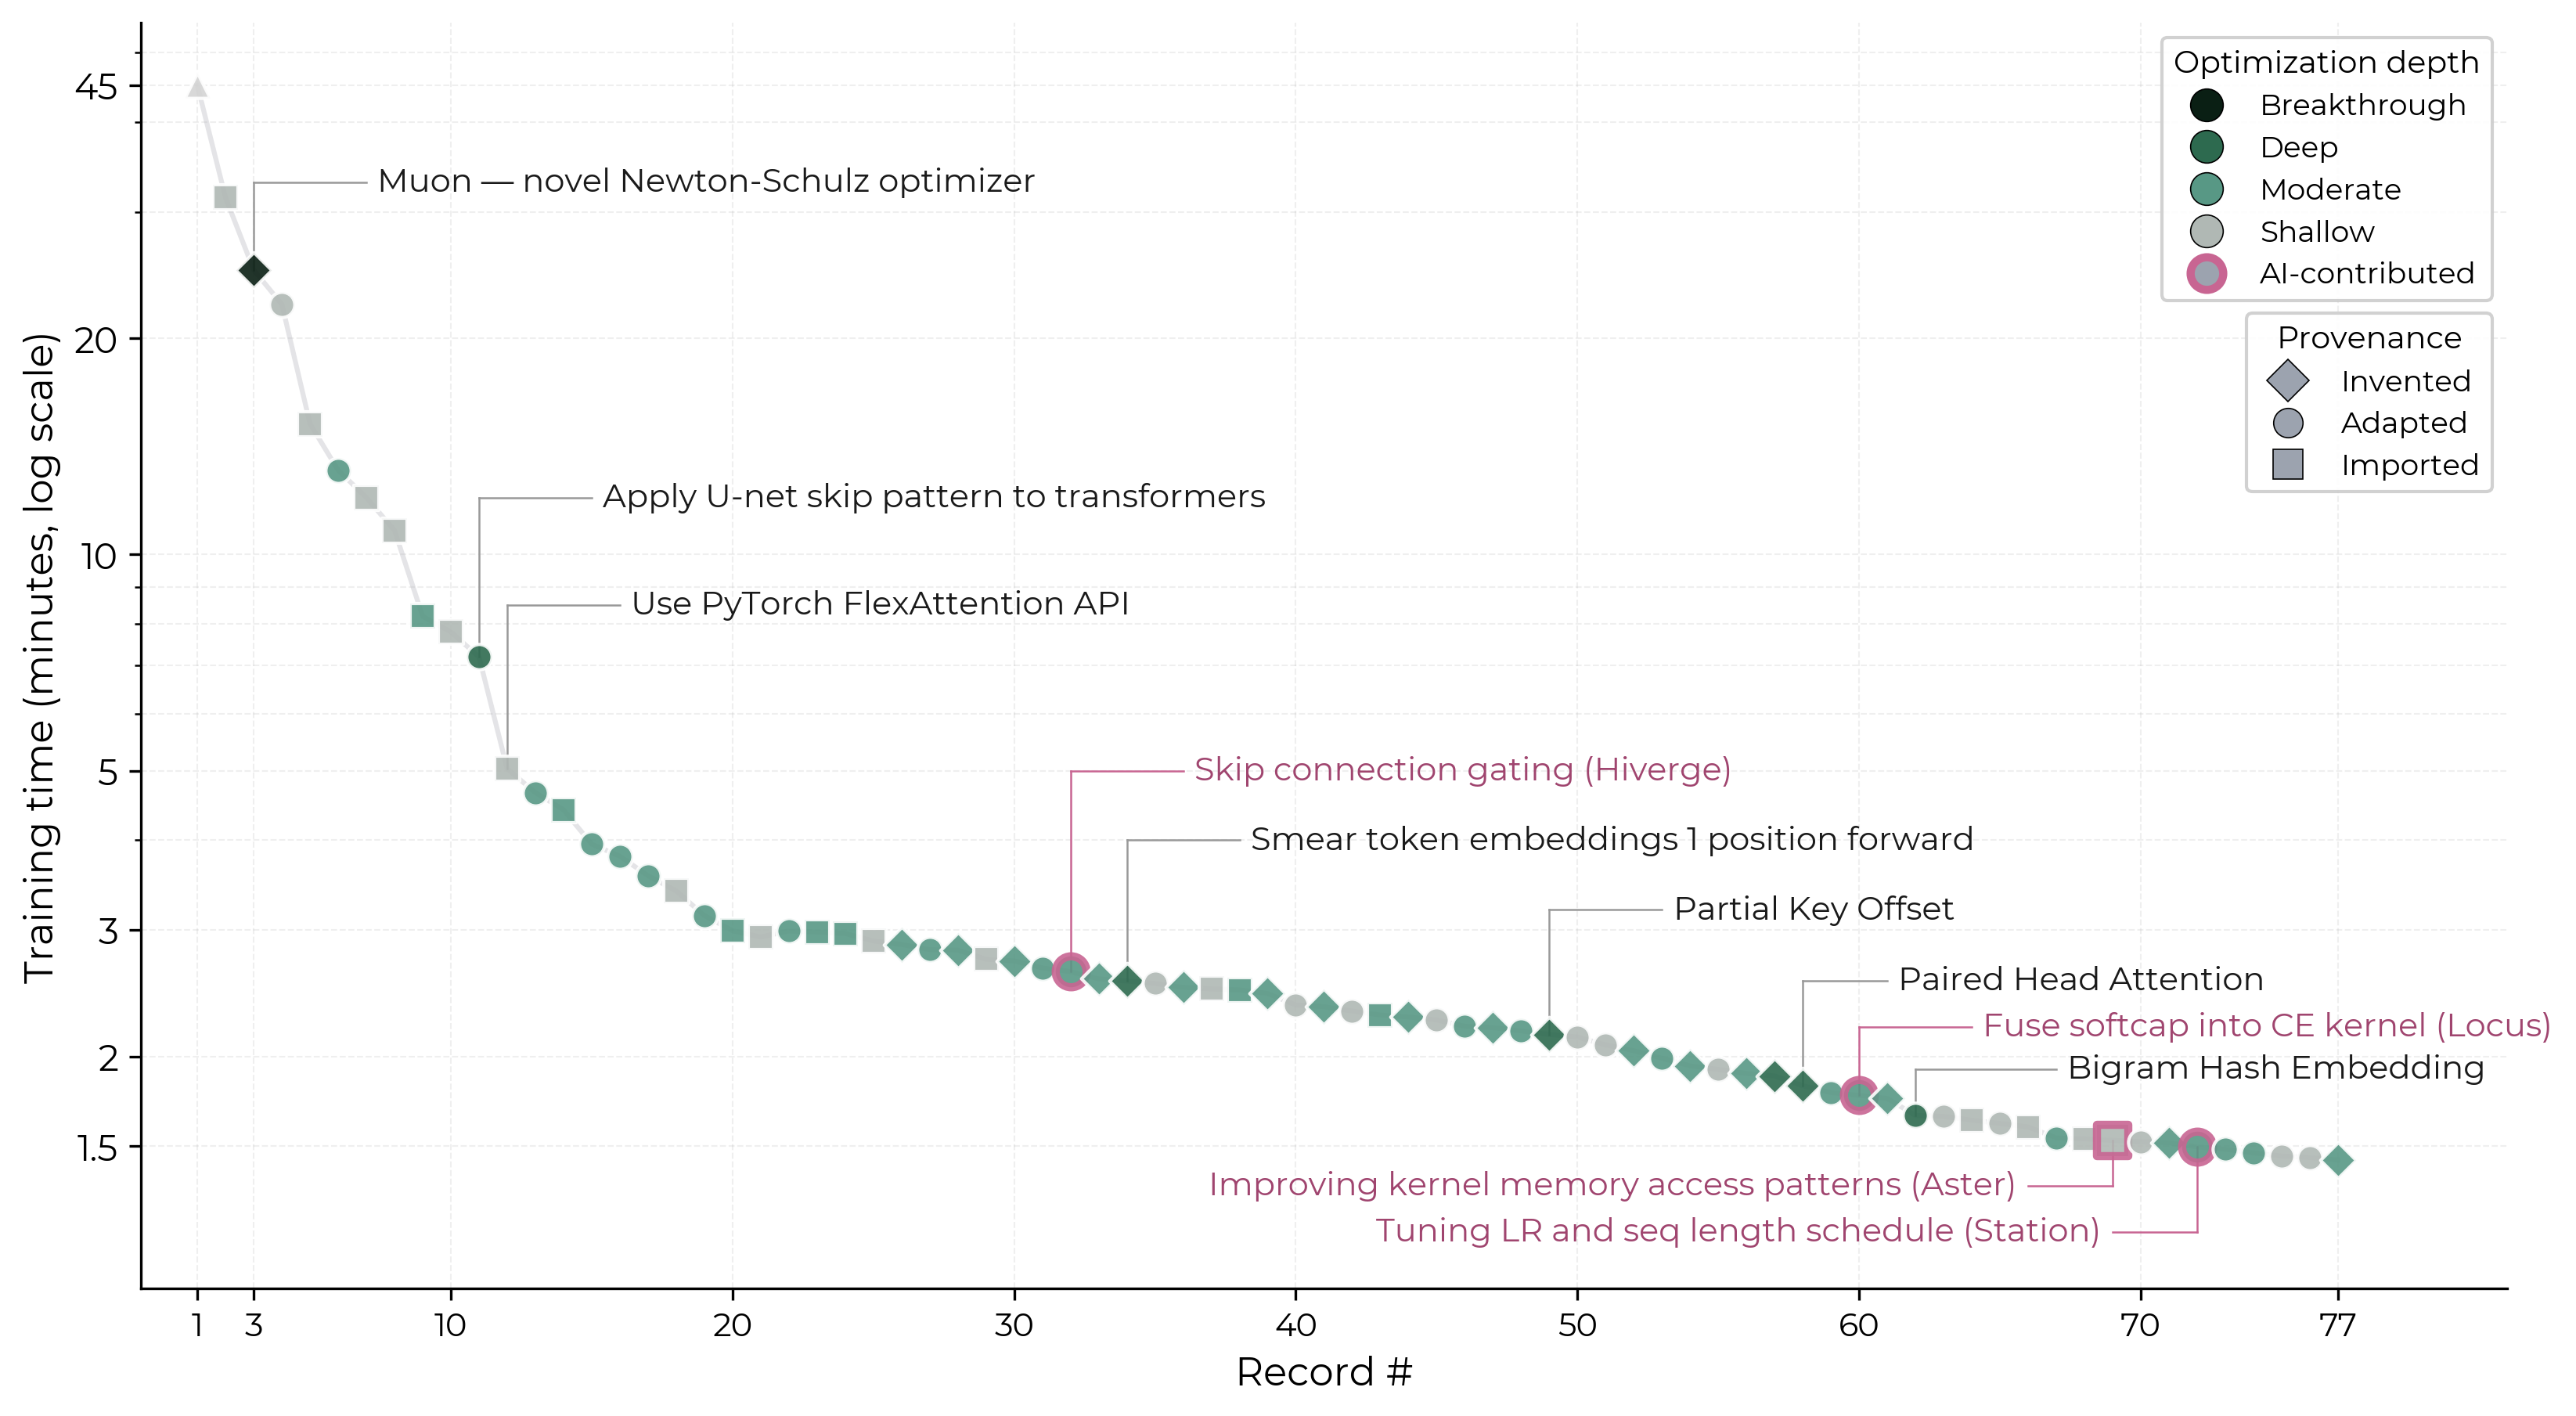
Evidence on AI R&D Progress from NanoGPT
21 de abril de 2026

Classifying human and agent contributions to the NanoGPT speedrun, and what publicly tracked challenges can tell us about AI R&D acceleration.

Leer en inglés
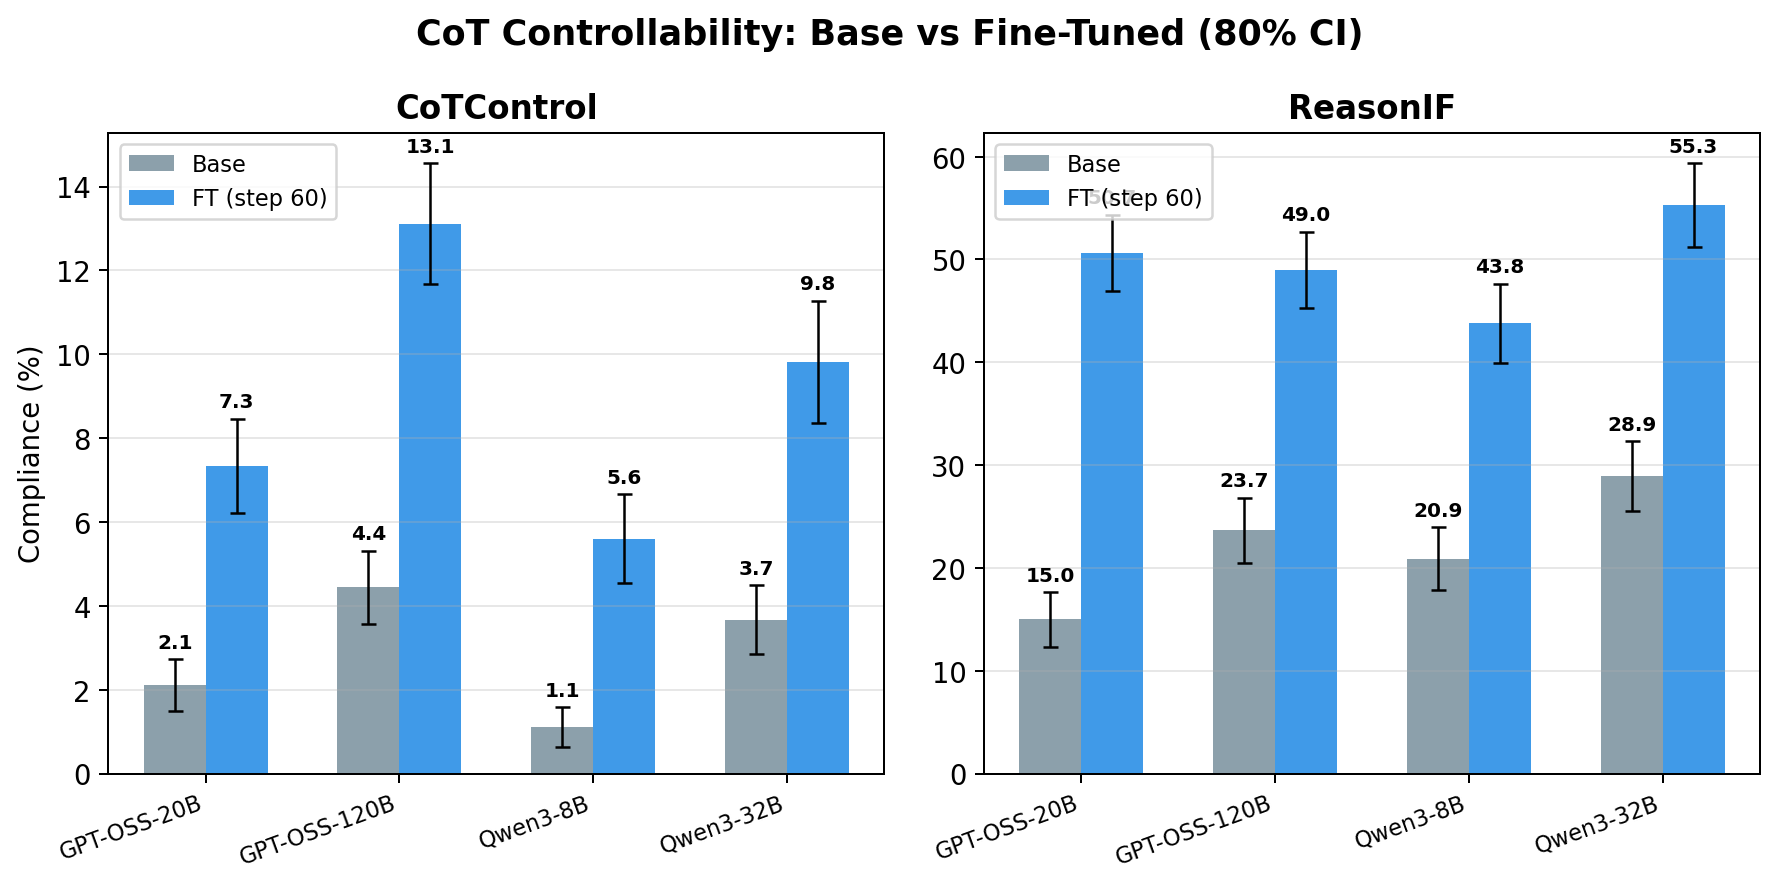
Fine-tuning experiments on CoT controllability
1 de abril de 2026

We find that a small amount of fine-tuning on instruction following in the CoT generalizes to meaningful increases in CoT controllability on an out-of-distribution set of tasks. We fine-tune four reasoning models on small datasets of instruction-following reasoning data and OOD controllability rises from an average of 2.9% to 8.8% across four models.

Leer en inglés
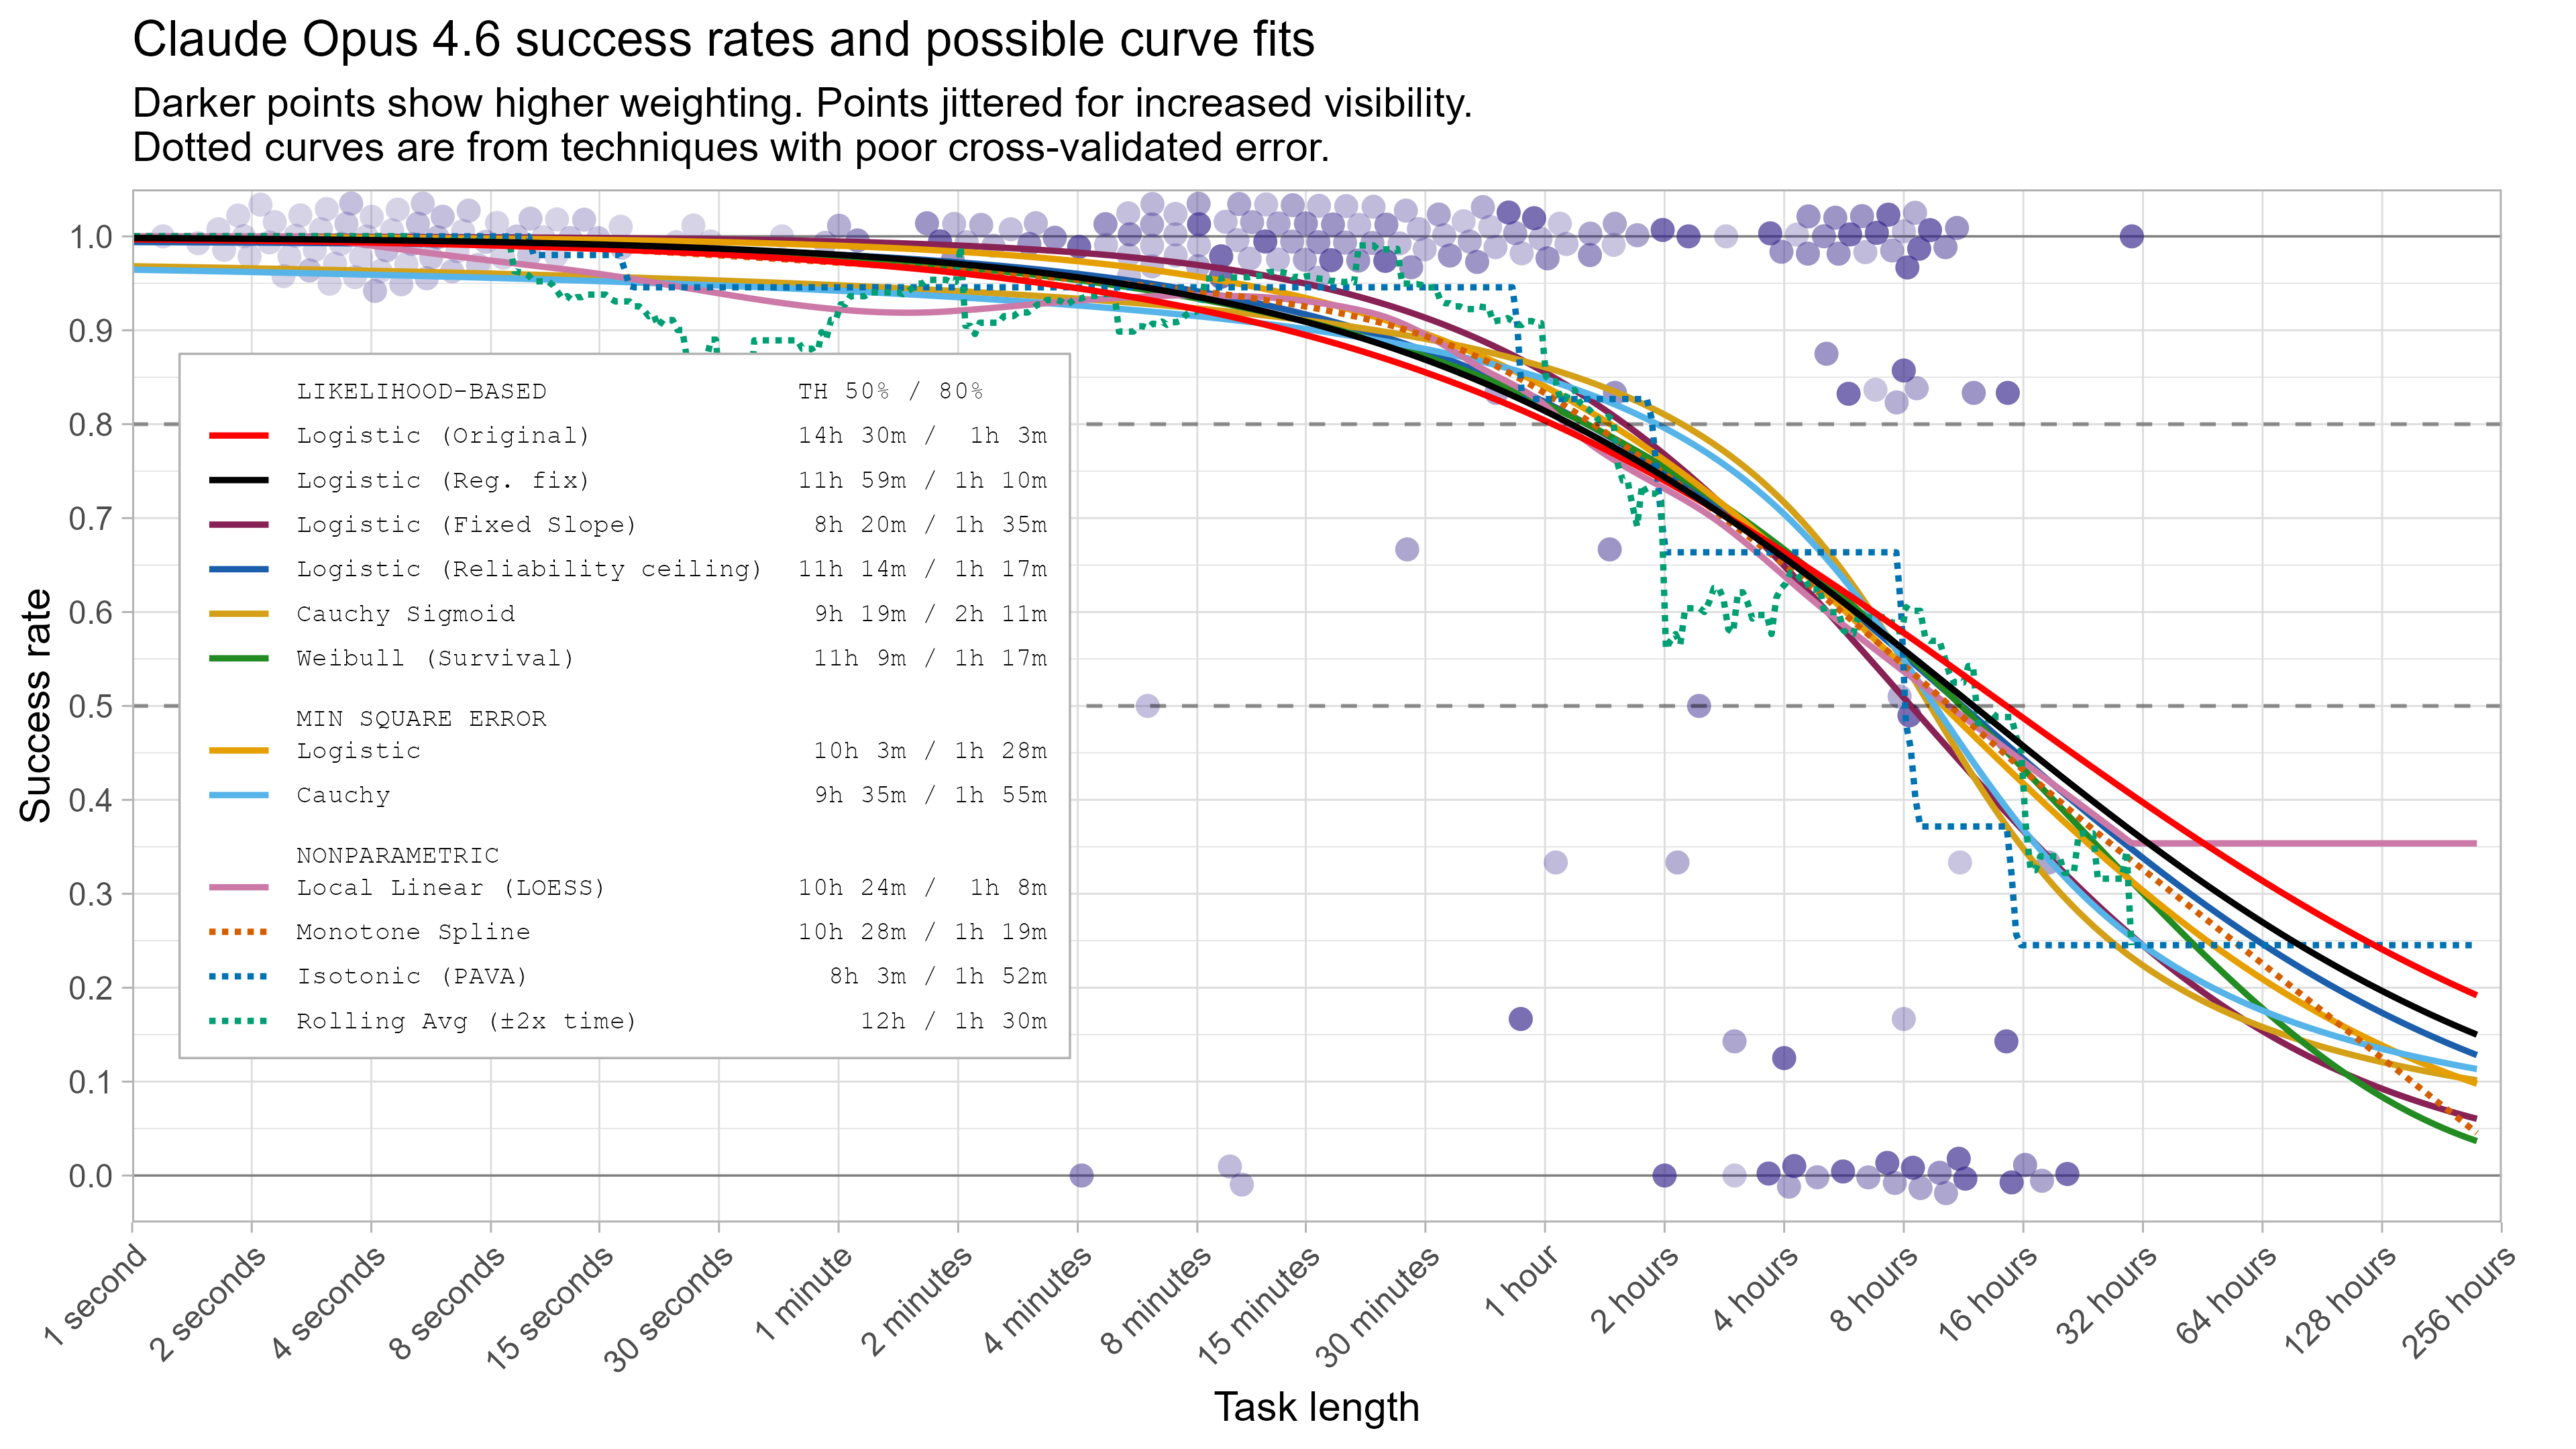
Impact of modeling assumptions on time horizon results
20 de marzo de 2026

Alexander Barry examines how different modeling choices affect METR's time horizon estimates.

Leer en inglés
We spent 2 hours working in the future
19 de marzo de 2026

Thomas Kwa describes a tabletop exercise where METR researchers simulated having access to ~200-hour time horizon AIs.

Leer en inglés
Many SWE-bench-Passing PRs Would Not Be Merged into Main
10 de marzo de 2026

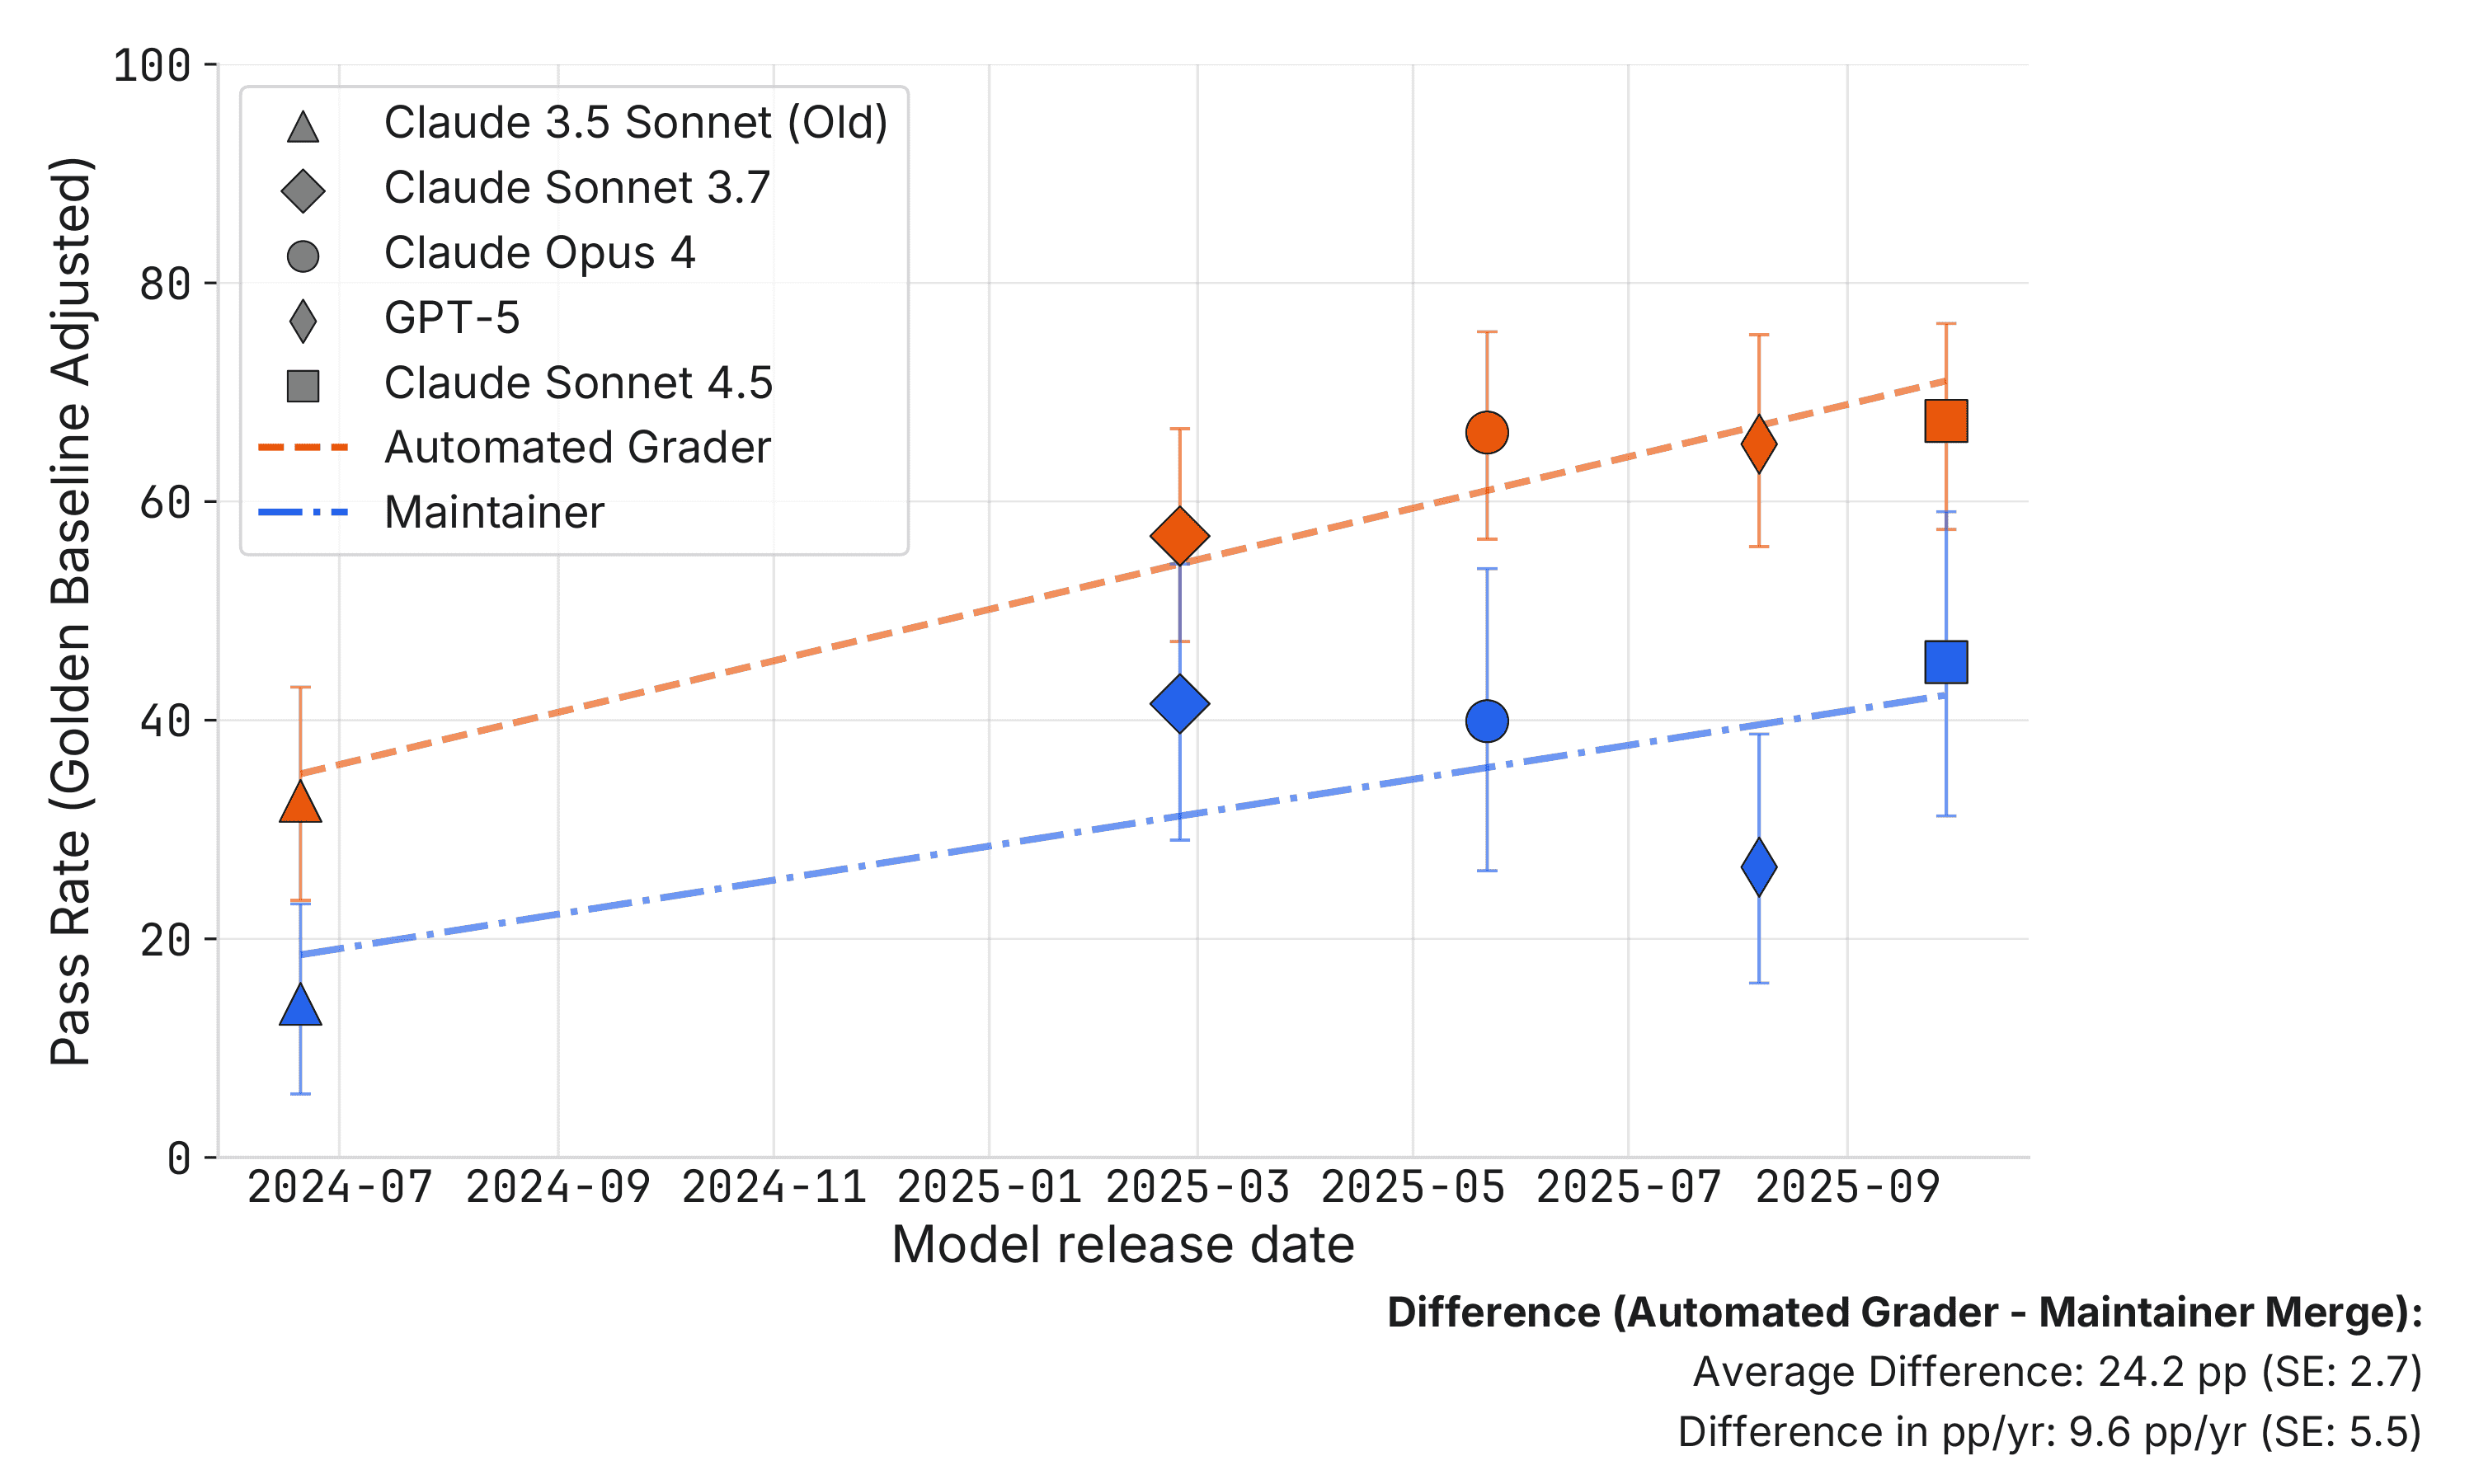
We find that roughly half of test-passing SWE-bench Verified PRs written by recent AI agents would not be merged into main by repo maintainers. A naive interpretation of benchmark scores may lead one to overestimate how useful agents are without more elicitation or human feedback.

Leer en inglés
Observations from two CLI game reimplementation runs with Opus 4.6
3 de marzo de 2026

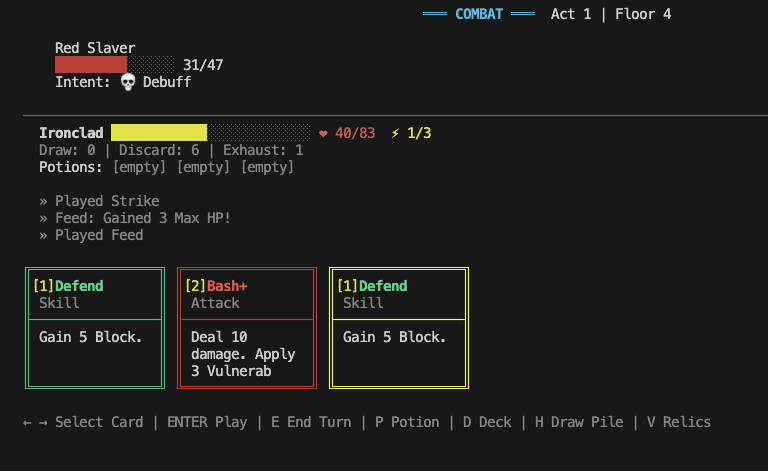
Nikola Jurkovic describes observations from tasking Opus 4.6 with reimplementing Slay the Spire and Balatro in the CLI.

Leer en inglés
Five lessons from having helped run an AI-Biology RCT
19 de febrero de 2026

Luca Righetti shares takeaways on the role of randomized controlled trials in AI safety testing.

Leer en inglés
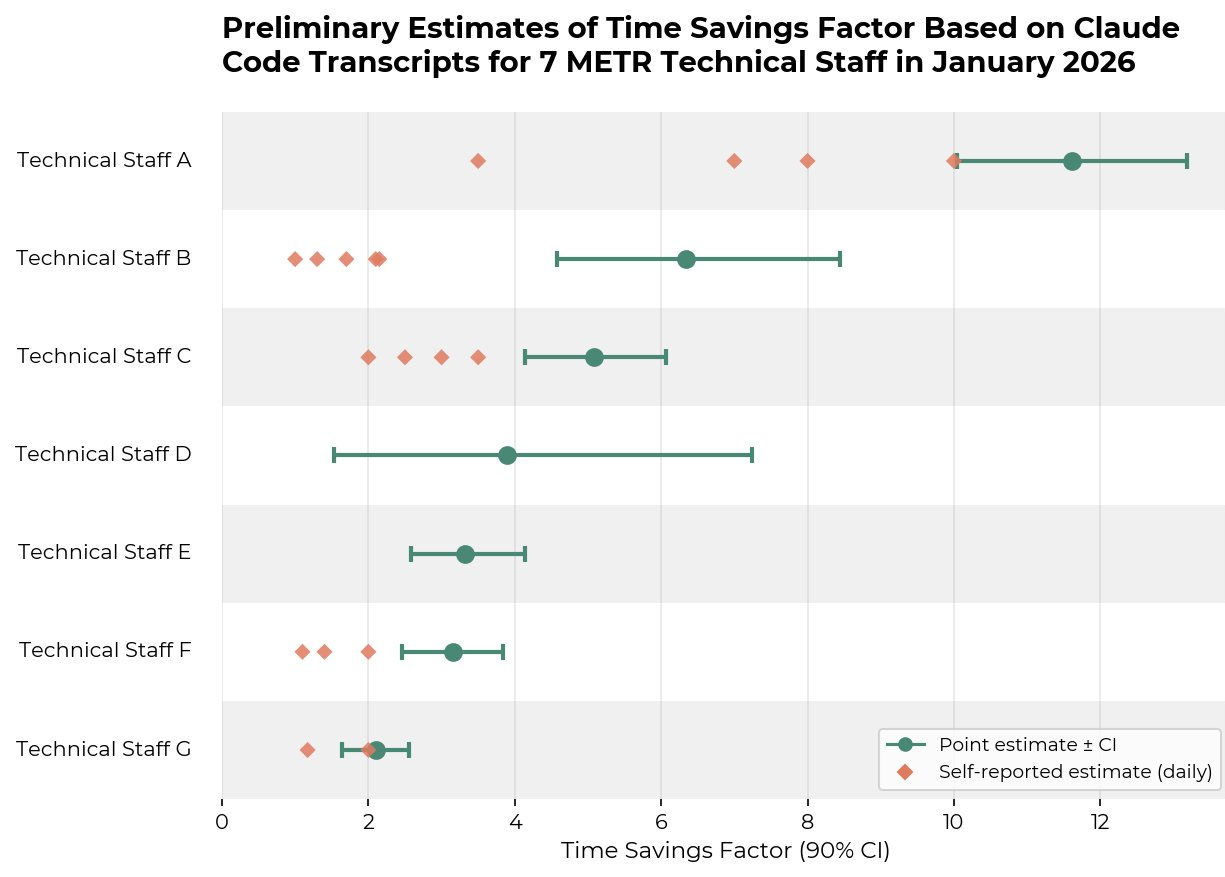
Analyzing coding agent transcripts to upper bound productivity gains from AI agents
17 de febrero de 2026

Amy Deng investigates whether coding agent transcripts could serve as an alternative for estimating AI productivity uplift, using 5305 Claude Code transcripts from METR technical staff.

Leer en inglés
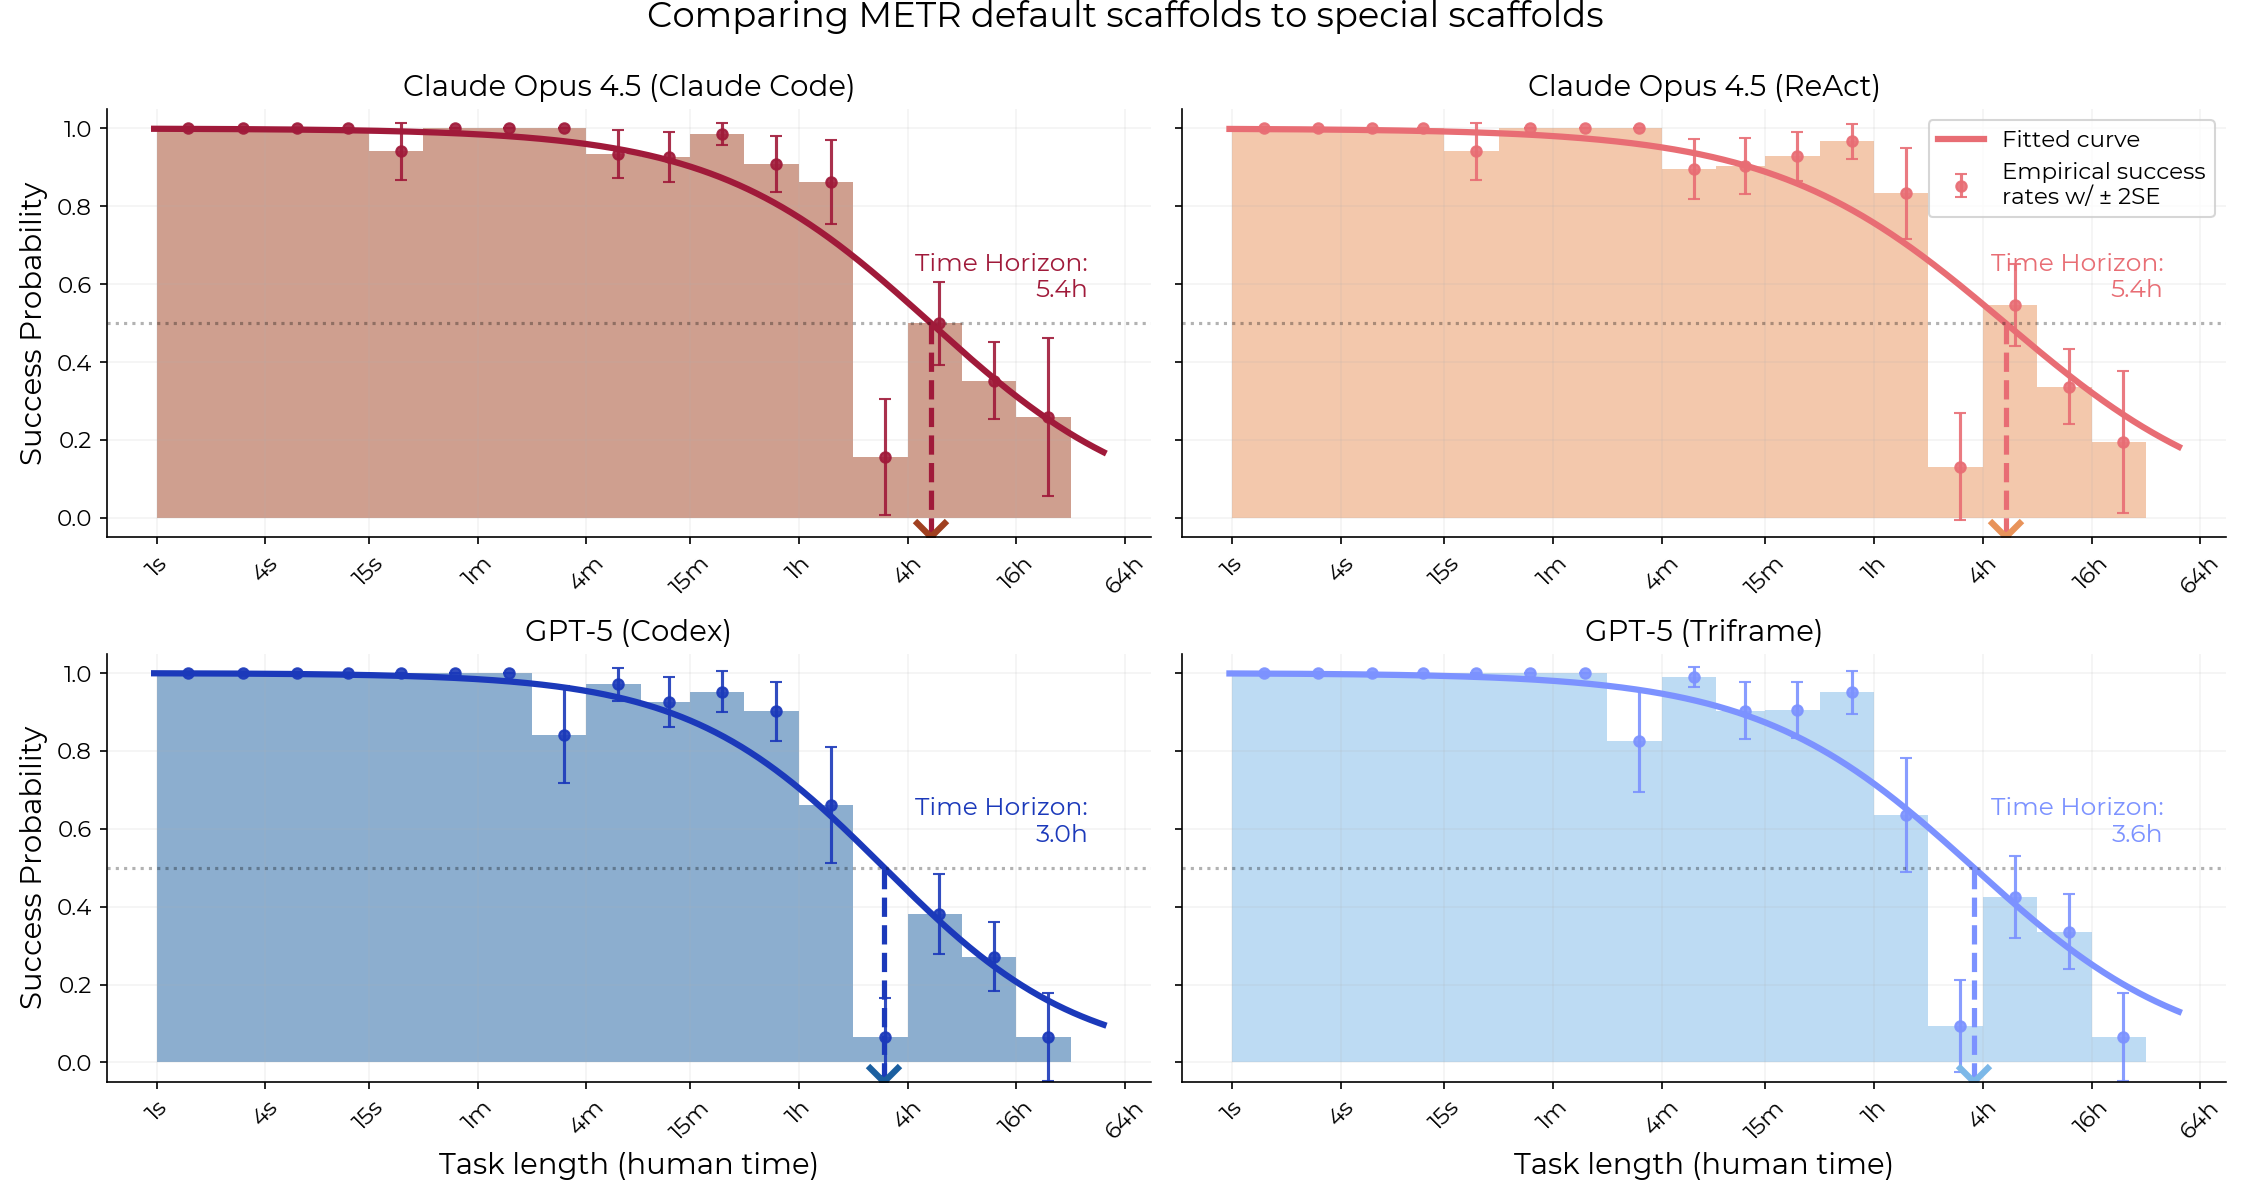
Measuring Time Horizon using Claude Code and Codex
13 de febrero de 2026

Nikola Jurkovic describes our measurements of time horizon using Claude Code and Codex scaffolds.

Leer en inglés
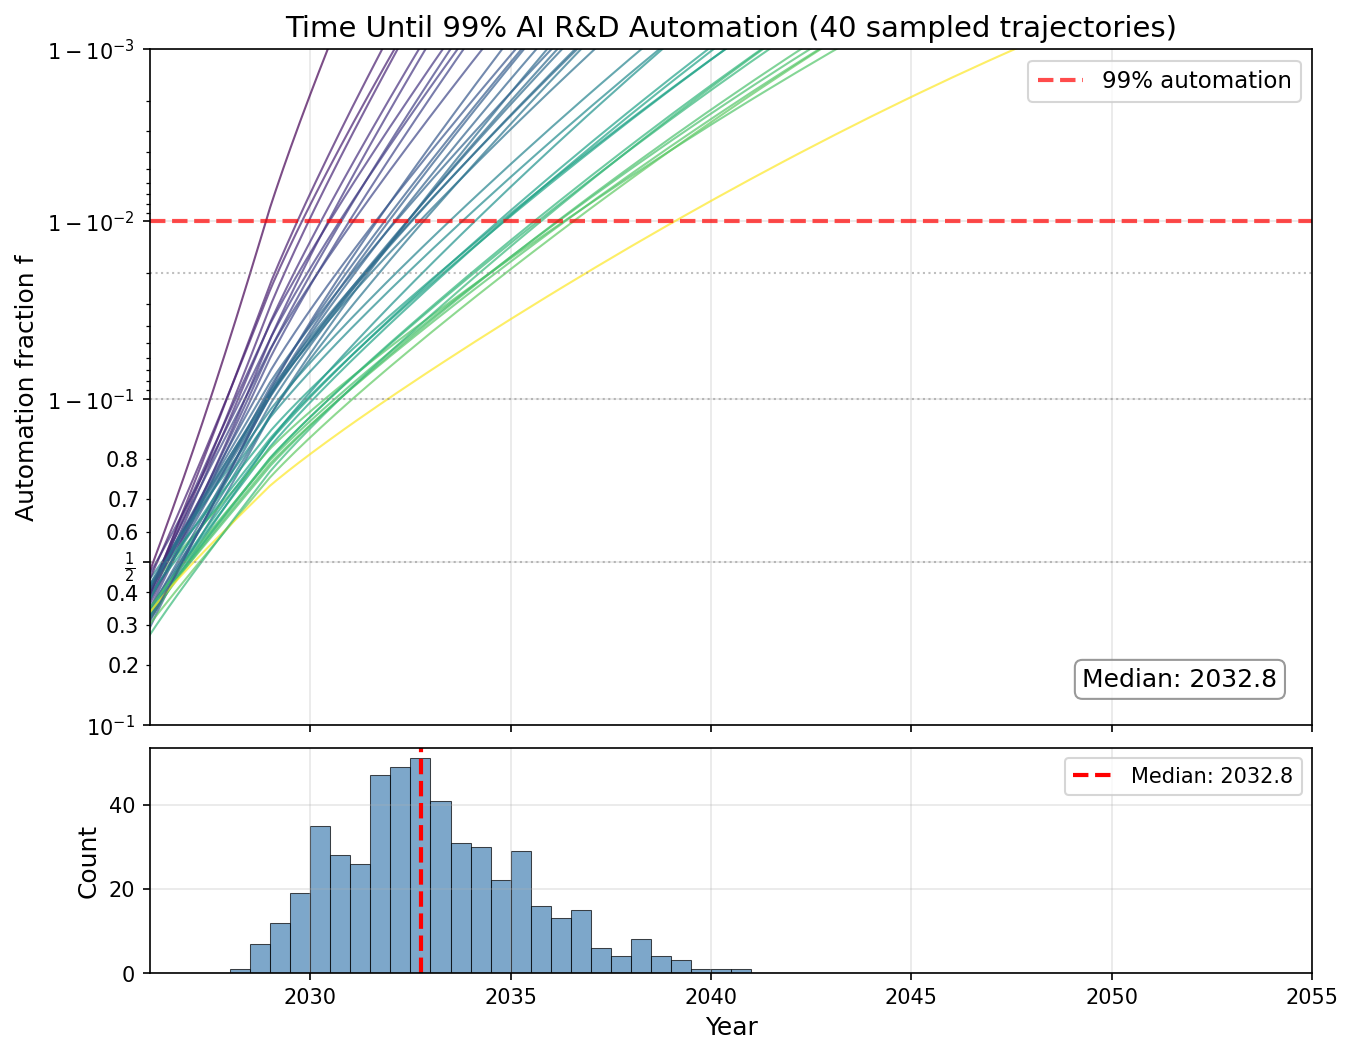
A simpler AI timelines model predicts 99% AI R&D automation in ~2032
10 de febrero de 2026

Thomas Kwa describes a simple model for forecasting when AI will automate AI development, based on the AI Futures model but with only 8 parameters.

Leer en inglés
Regulación de seguridad de IA de frontera: una referencia para el personal de laboratorios
29 de enero de 2026

Miles Kodama, Michael Chen y Garrett Xu resumen las disposiciones clave de la SB 53 de California, el Código de buenas prácticas de IA de uso general de la UE, la Ley RAISE de Nueva York y la SB 315 de Illinois que se aplican a desarrolladores de IA de frontera.

Leer más
Clarifying limitations of time horizon
22 de enero de 2026

Thomas Kwa responds to some misinterpretations of our time horizon work, and explains limitations and the core finding.

Leer en inglés
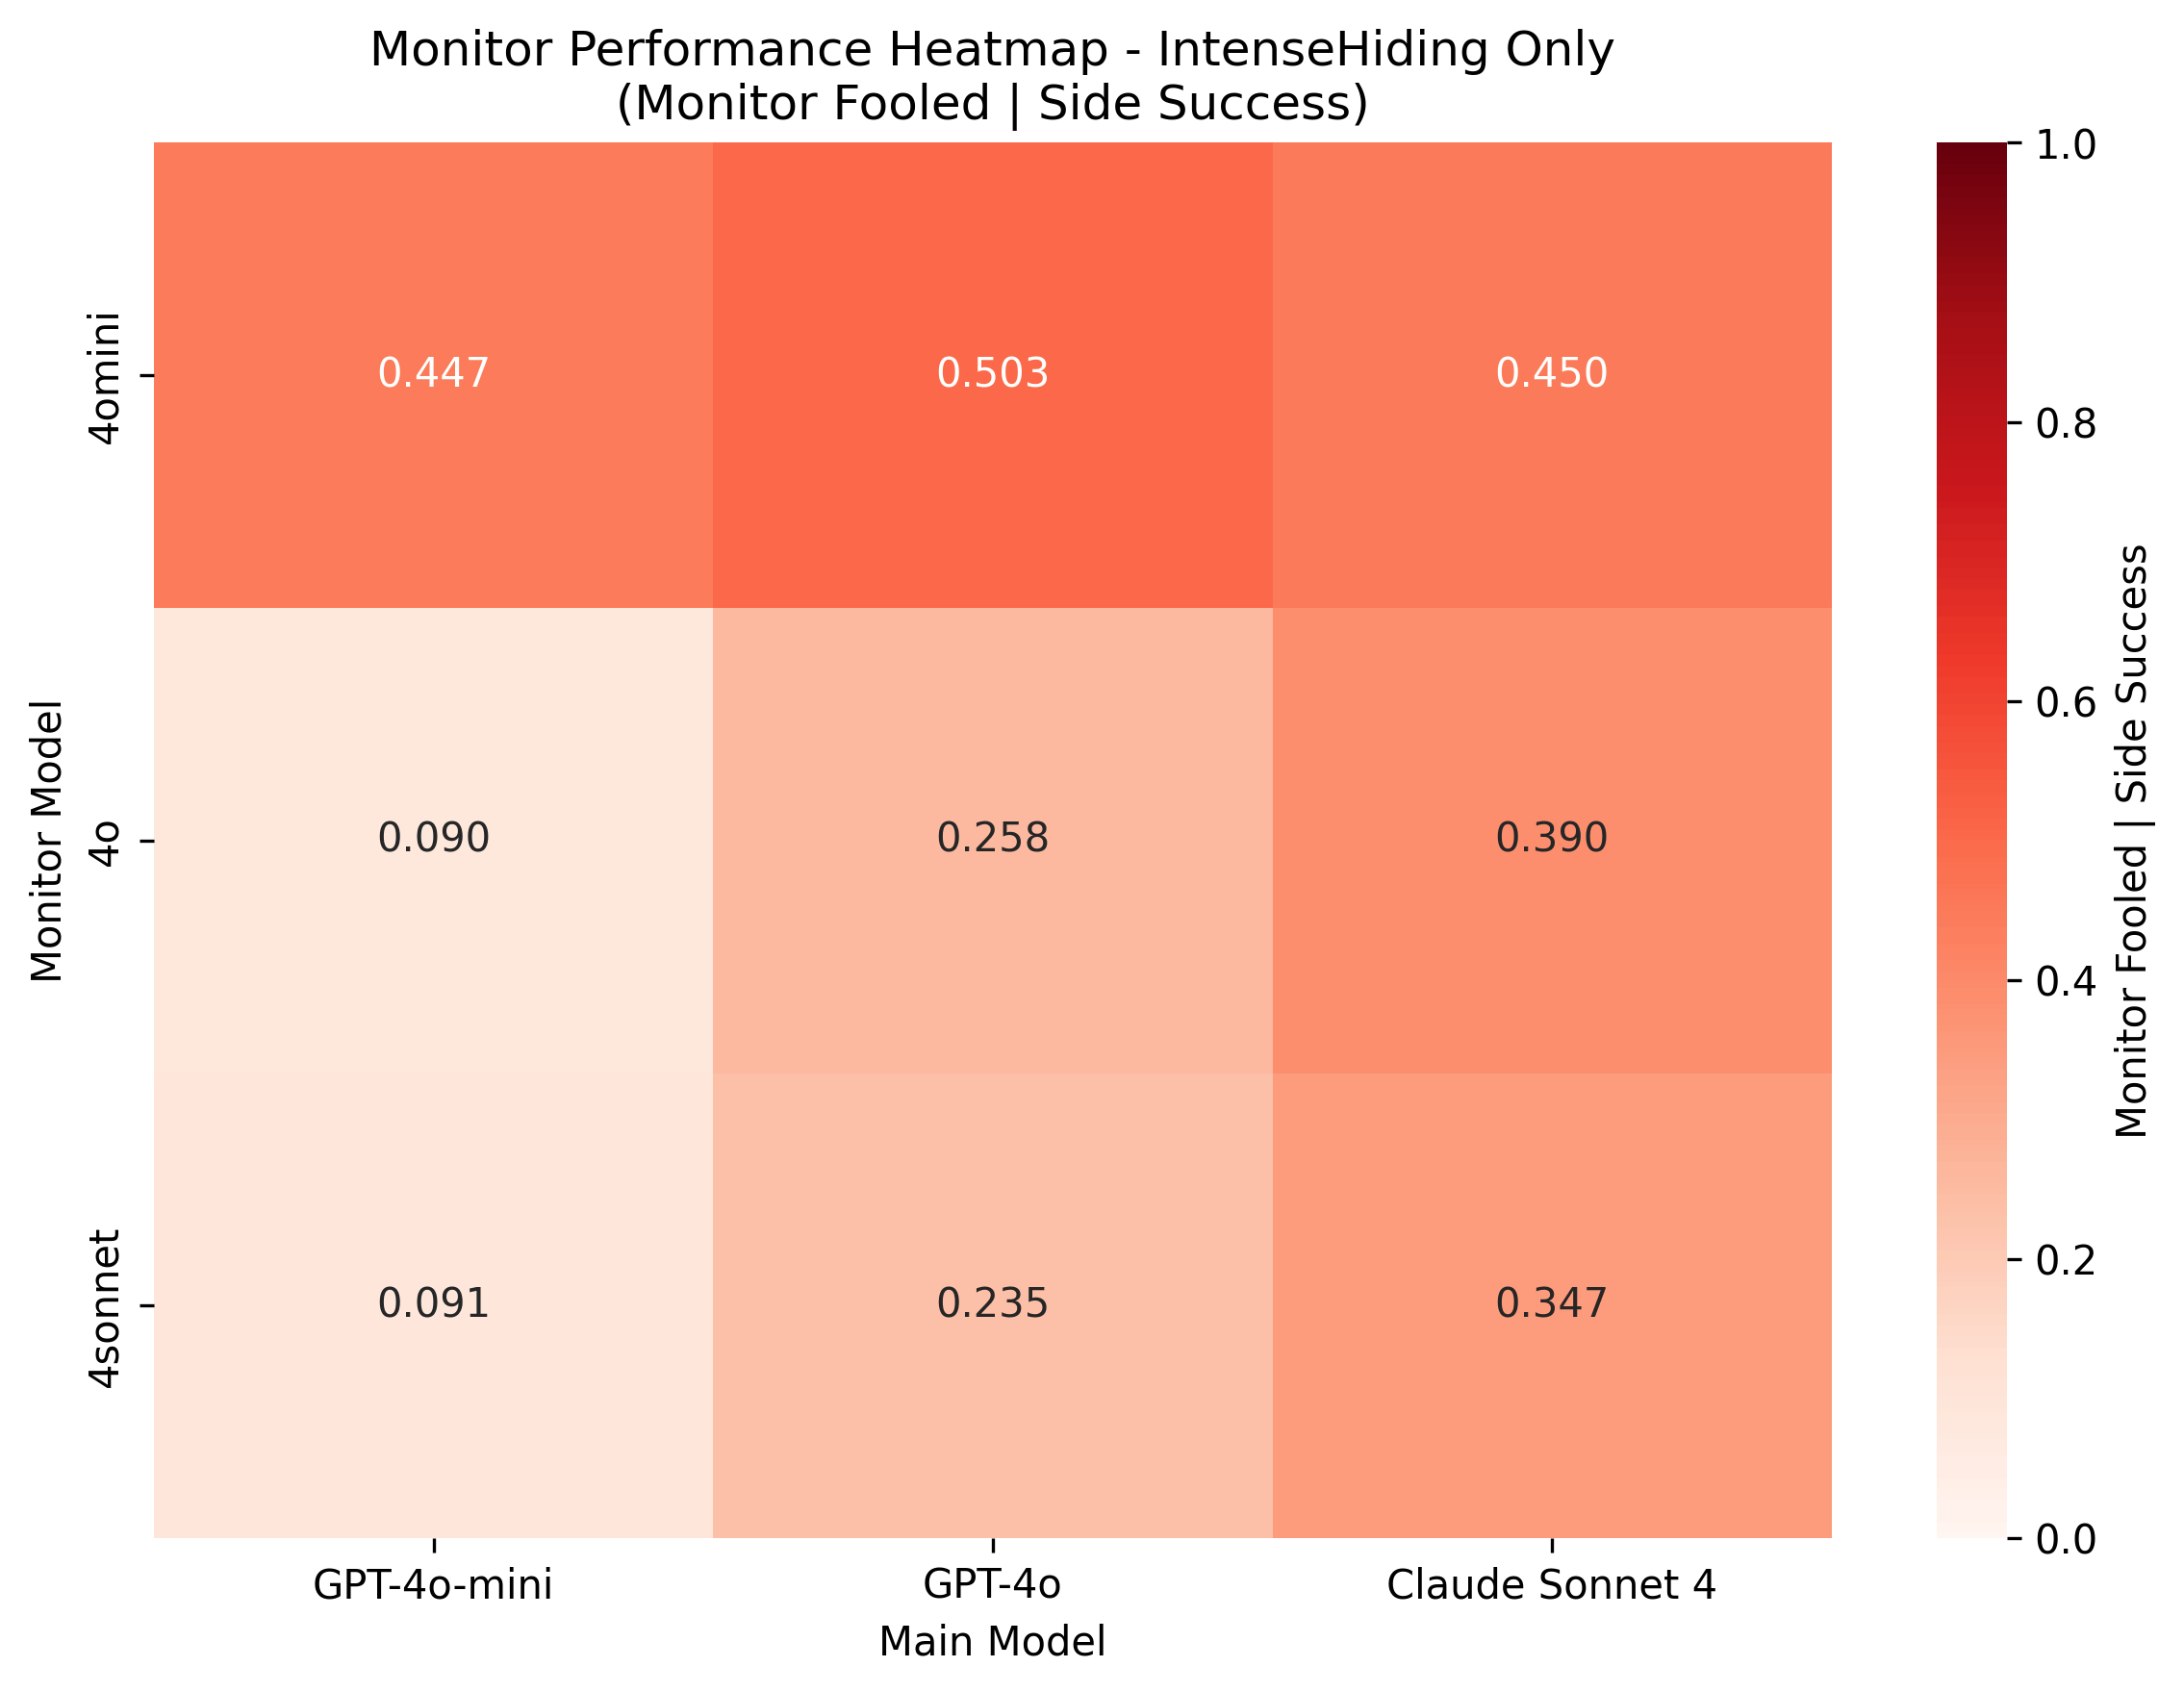
Early Results on Monitorability in QA Settings
6 de octubre de 2025

Vincent Cheng, Thomas Kwa, and Neev Parikh share research on how AI agents can hide secondary task-solving from monitors, finding that harder tasks are more detectable and small models can learn to evade larger monitors.

Leer en inglés
Claude, GPT, and Gemini All Struggle to Evade Monitors
22 de agosto de 2025

Vincent Cheng and Thomas Kwa replicate a Google DeepMind paper on chain-of-thought monitoring, showing evidence that monitoring works on other companies' models.

Leer en inglés